The use case: how Bytefuse deploys Weights & Biases
Bytefuse uses W&B Weave to trace and debug the system of agents behind Maski, its WhatsApp-based AI tutor for South African students and teachers. It also uses Weave to compare custom and third-party models, collect user thumbs-up/thumbs-down feedback, and uses W&B Models and Registry to log experiments and automate model deployment and regression testing.
In the customer’s words
W&B Weave Traces makes it super easy to see from user input what every single route that message went through in our agentic system until it got back to the user. So when something goes wrong, it's a very easy debug. Especially in this LLM world, where things are so unpredictable, you really need to know what's going on. That's where W&B fits in for us.Weights & Biases users in Artificial Intelligence
Companies in the same sector, with public evidence.
 Aleph AlphaConfirmed
 CapturConfirmed
 CohereConfirmed
 DecartConfirmedGretelConfirmed
 Inverted AIConfirmed
Go straight to the source
Based on Weights & Biases’s published case study. We check the public evidence; the results are reported by the vendor.
wandb.ai- Source published
- Apr 1, 2025
- Last checked
- Nov 11, 2026
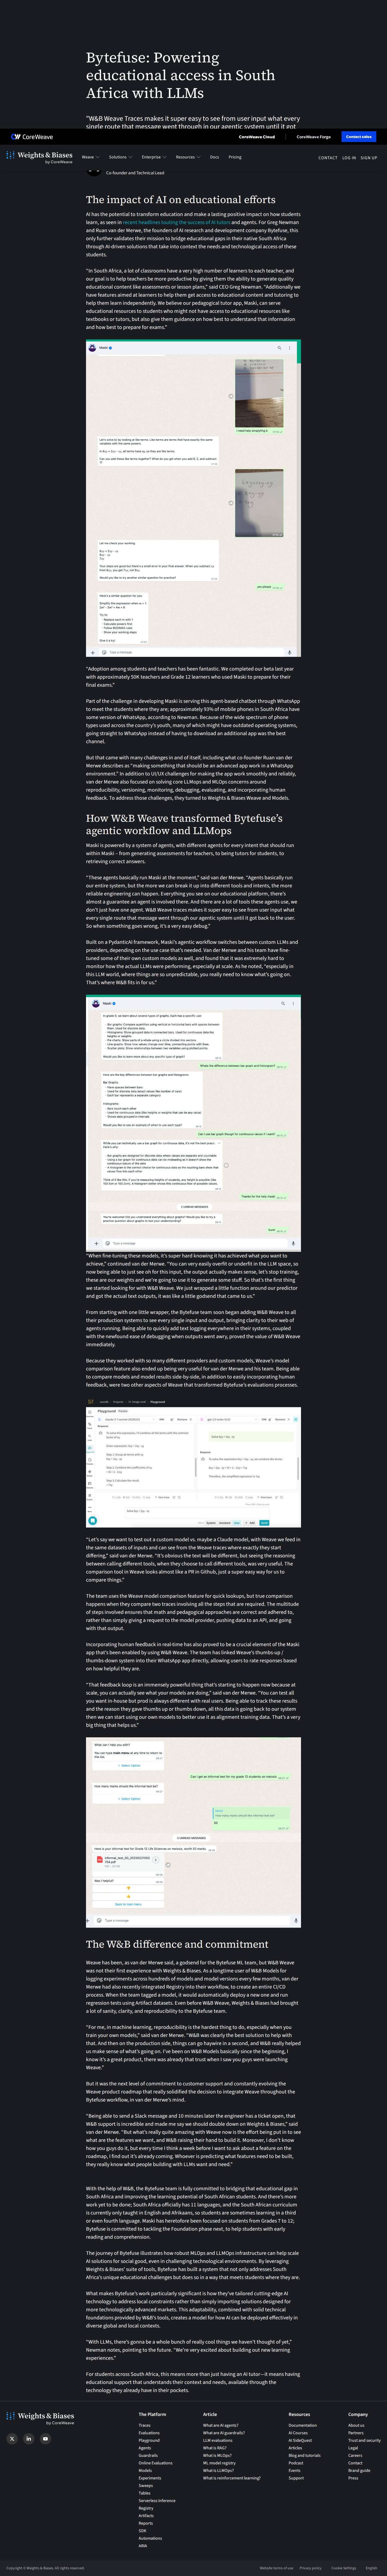 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The publication dateChecked
Read from the page’s own metadata, never guessed.
- Bytefuse uses Weights & BiasesChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
Built on a PydanticAI framework, Maski’s agentic workflow switches between custom LLMs and providers, depending on the use case that’s needed. Van der Merwe and his team have fine-tuned some of their own custom models as well, and found that it was extremely hard to monitor how the actual LLMs were performing, especially at scale.