The use case: how Coactive deploys Anyscale
Coactive AI runs its multimodal AI platform for image and video analysis on Anyscale, using Ray Serve in a Bring Your Own Cloud setup on its Kubernetes clusters across AWS and Azure. It uses fractional GPU allocation and autoscaling to serve low-latency search and large batch processing workloads.
More reported results
Figures published in Anyscale’s case study. They are not independently measured by usedby.
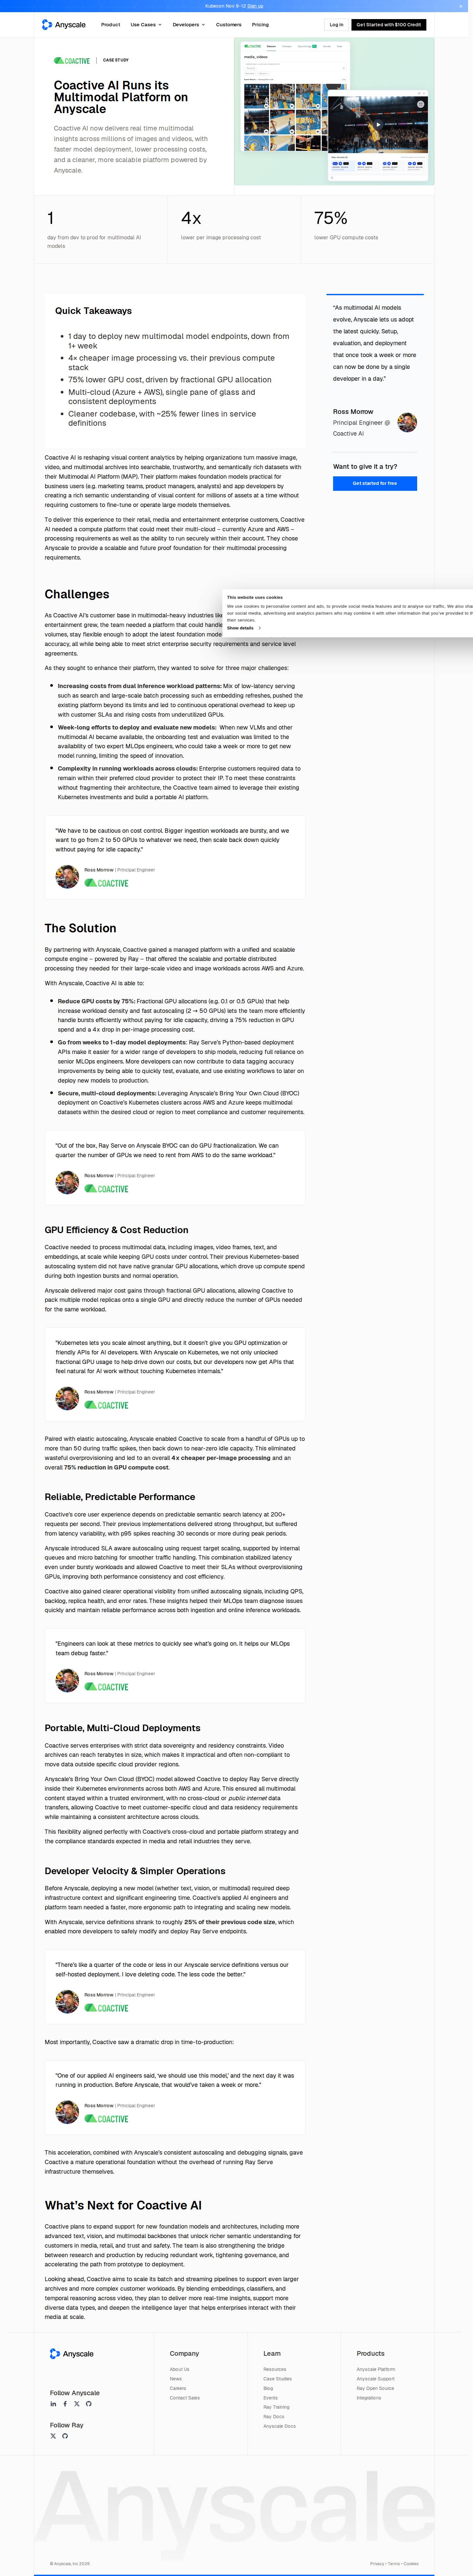
driving a 75% reduction in GPU spend and a 4x drop in per-image processing cost.
1 day to deploy new multimodal model endpoints, down from 1+ week
With Anyscale, service definitions shrank to roughly 25% of their previous code size, which enabled more developers to safely modify and deploy Ray Serve endpoints.
In the customer’s words
One of our applied AI engineers said, ‘we should use this model,’ and the next day it was running in production. Before Anyscale, that would’ve taken a week or more.Anyscale users in Artificial Intelligence
Companies in the same sector, with public evidence.
 Bedrock RoboticsConfirmed
 Physical IntelligenceConfirmed
 RunwayConfirmed
 Character.aiObserved
 ReflectionObserved
 Torc RoboticsObserved
Go straight to the source
Based on Anyscale’s published case study. We check the public evidence; the results are reported by the vendor.
anyscale.com- Last checked
- Nov 7, 2026
 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 75%Checked
Printed word for word on the page, near the name of Coactive.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Coactive.
- Coactive uses AnyscaleChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
Fractional GPU allocations (e.g. 0.1 or 0.5 GPUs) that help increase workload density and fast autoscaling (2 → 50 GPUs) lets the team more efficiently handle bursts efficiently without paying for idle capacity, driving a 75% reduction in GPU spend and a 4x drop in per-image processing cost.