The use case: how Gretel deploys Weights & Biases
Gretel uses Weights & Biases to track, log and evaluate experiments while fine-tuning the LLMs and SLMs behind its Navigator synthetic data system across domains such as tabular data, healthcare records and financial records. This let the team launch new experiment batches frequently and run far more experiments before its first model launch.
More reported results
Figures published in Weights & Biases’s case study. They are not independently measured by usedby.
We went from running 3-5 experiments per week to completing 250 experiments in just 45 days before our first model launch
They were able to use synthetic datasets to help decrease their training data from a trillion to a billion tokens—a 1000x reduction—while maintaining model quality.
In the customer’s words
W&B’s logging and evaluation tools let us quickly identify gaps, make adjustments, and launch new experiment batches every few days. Instead of queuing up 5-10 experiments, we could now run 50-100 experiments in each compute block.Weights & Biases users in Artificial Intelligence
Companies in the same sector, with public evidence.
 Aleph AlphaConfirmed
 BytefuseConfirmed
 CapturConfirmed
 CohereConfirmed
 DecartConfirmed
 Inverted AIConfirmed
Go straight to the source
Based on Weights & Biases’s published case study. We check the public evidence; the results are reported by the vendor.
wandb.ai- Source published
- Jan 24, 2025
- Last checked
- Nov 11, 2026
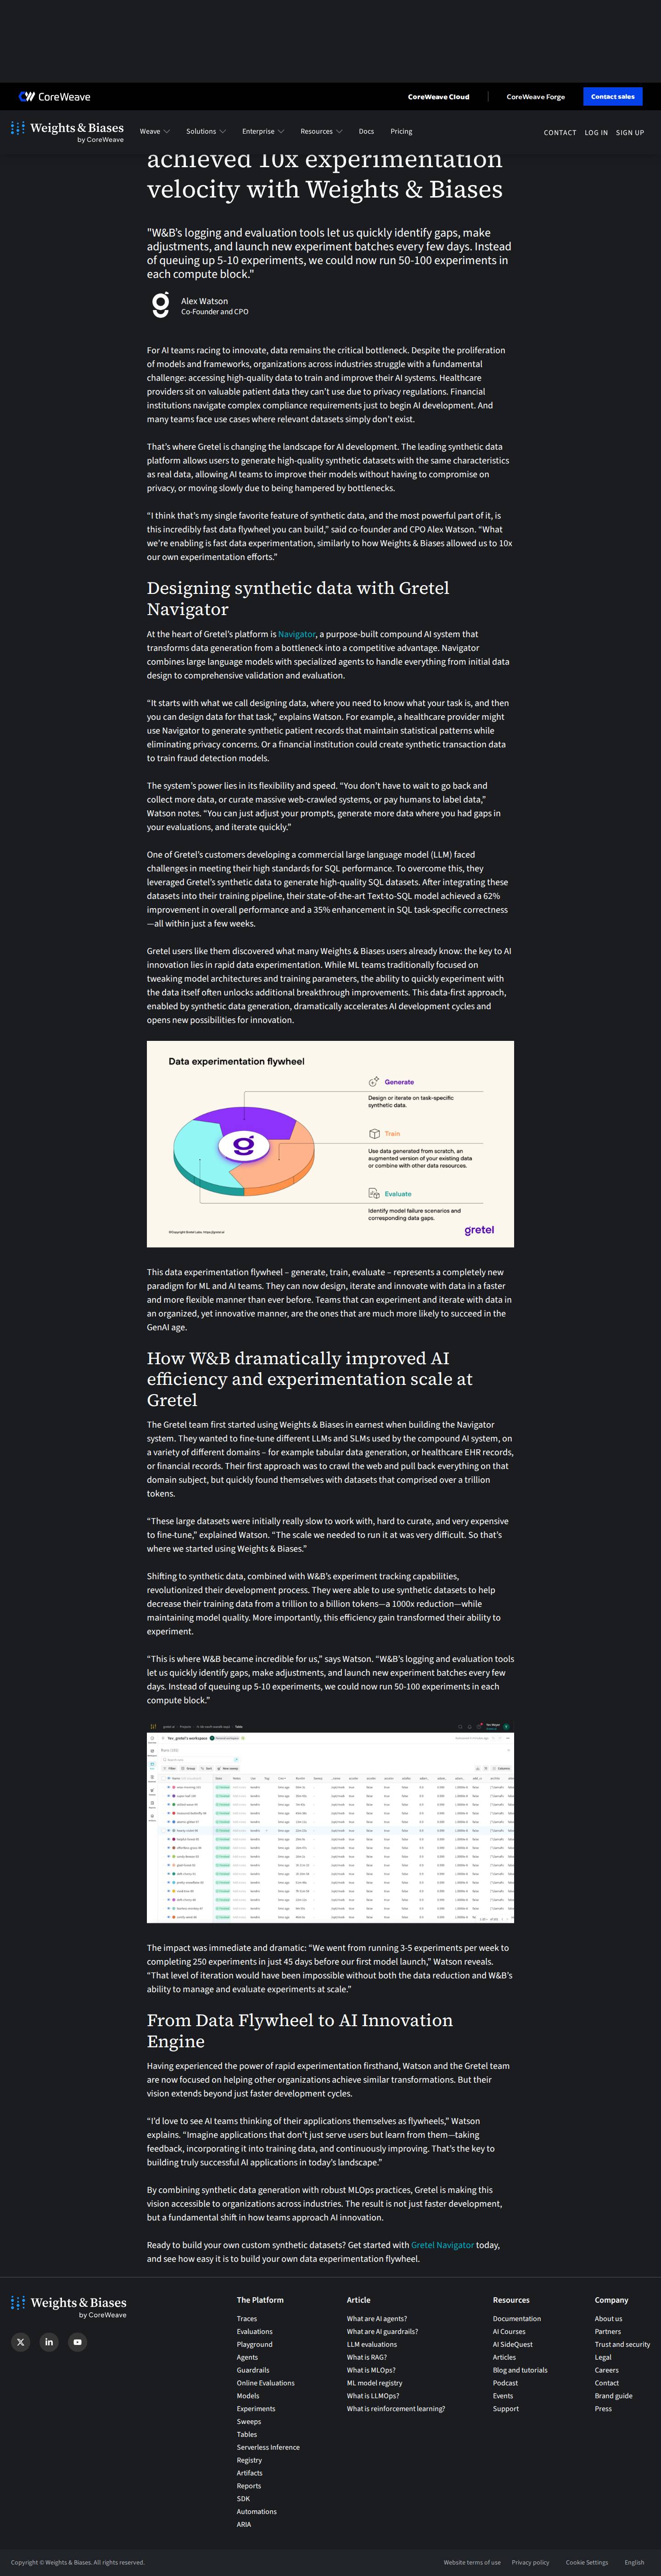 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 10xChecked
Printed word for word on the page, near the name of Gretel.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Gretel.
- The publication dateChecked
Read from the page’s own metadata, never guessed.
- Gretel uses Weights & BiasesChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
W&B’s logging and evaluation tools let us quickly identify gaps, make adjustments, and launch new experiment batches every few days. Instead of queuing up 5-10 experiments, we could now run 50-100 experiments in each compute block.