The use case: how Sentient deploys Fireworks AI
Sentient serves its Dobby-70B open-source language model, which powers the multi-agent Sentient Chat assistant and the Dobby Arena, on Fireworks AI. It uses serverless endpoints for iteration and dedicated custom deployments for real-time, high-concurrency inference.
More reported results
Figures published in Fireworks AI’s case study. They are not independently measured by usedby.
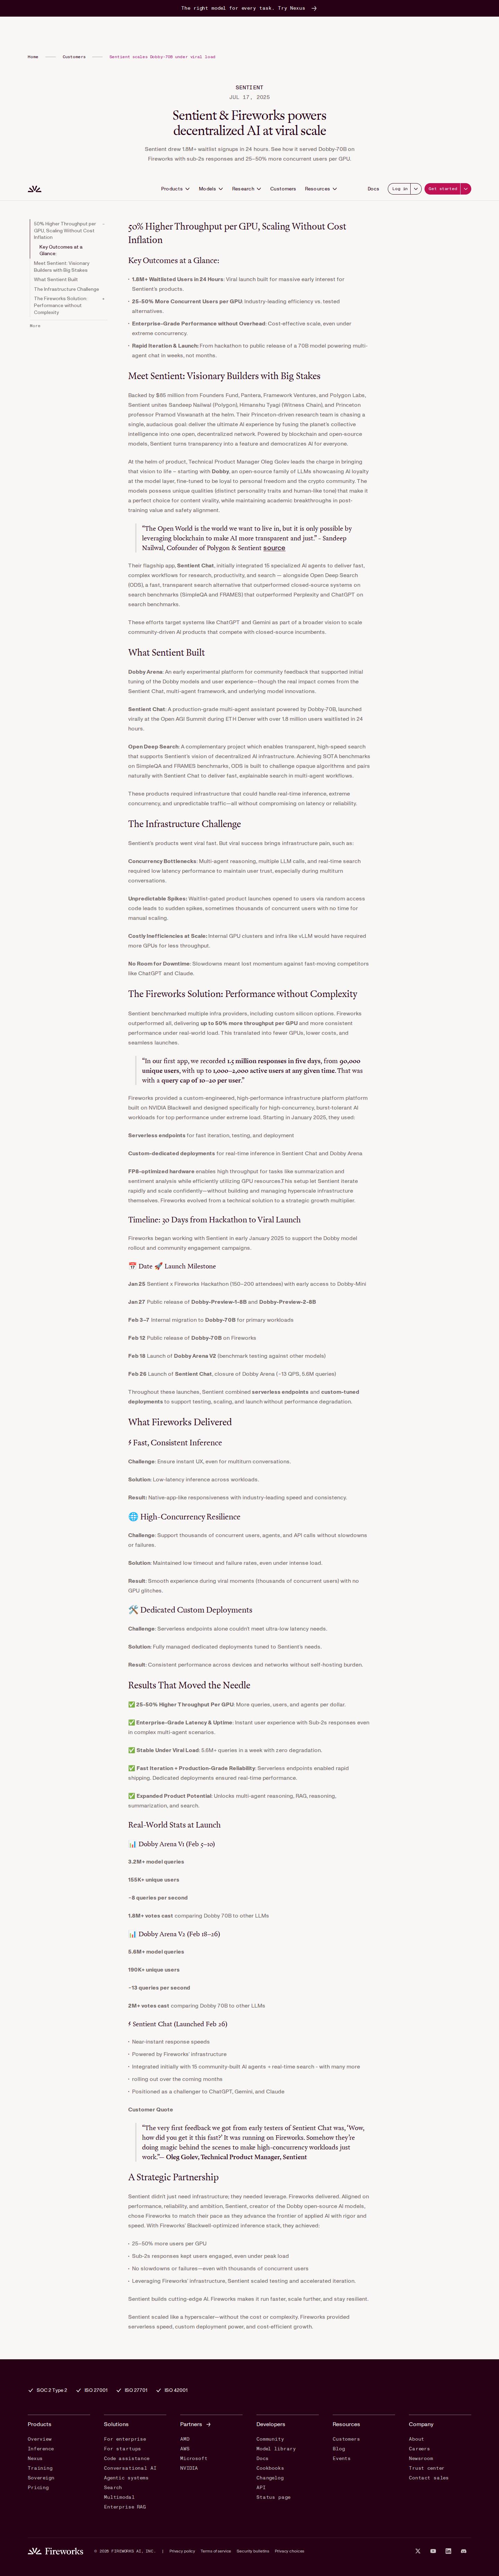
✅ Stable Under Viral Load: 5.6M+ queries in a week with zero degradation.
✅ Enterprise-Grade Latency & Uptime: Instant user experience with Sub-2s responses even in complex multi-agent scenarios.
In the customer’s words
The very first feedback we got from early testers of Sentient Chat was, ‘Wow, how did you get it this fast?’ It was running on Fireworks. Somehow they’re doing magic behind the scenes to make high-concurrency workloads just work.Fireworks AI users in Artificial Intelligence
Companies in the same sector, with public evidence.
See all Fireworks AI customers
Go straight to the source
Based on Fireworks AI’s published case study. We check the public evidence; the results are reported by the vendor.
fireworks.ai- Source published
- Jul 17, 2025
- Last checked
- Nov 6, 2026
 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 25-50%Checked
Printed word for word on the page, near the name of Sentient.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Sentient.
- The numbers in our summaryChecked
Each one is printed on the page.
- The publication dateChecked
Read from the page’s own metadata, never guessed.
- Sentient uses Fireworks AIChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
Sentient benchmarked multiple infra providers, including custom silicon options. Fireworks outperformed all, delivering up to 50% more throughput per GPU and more consistent performance under real-world load.