The use case: how Verra deploys Upstage
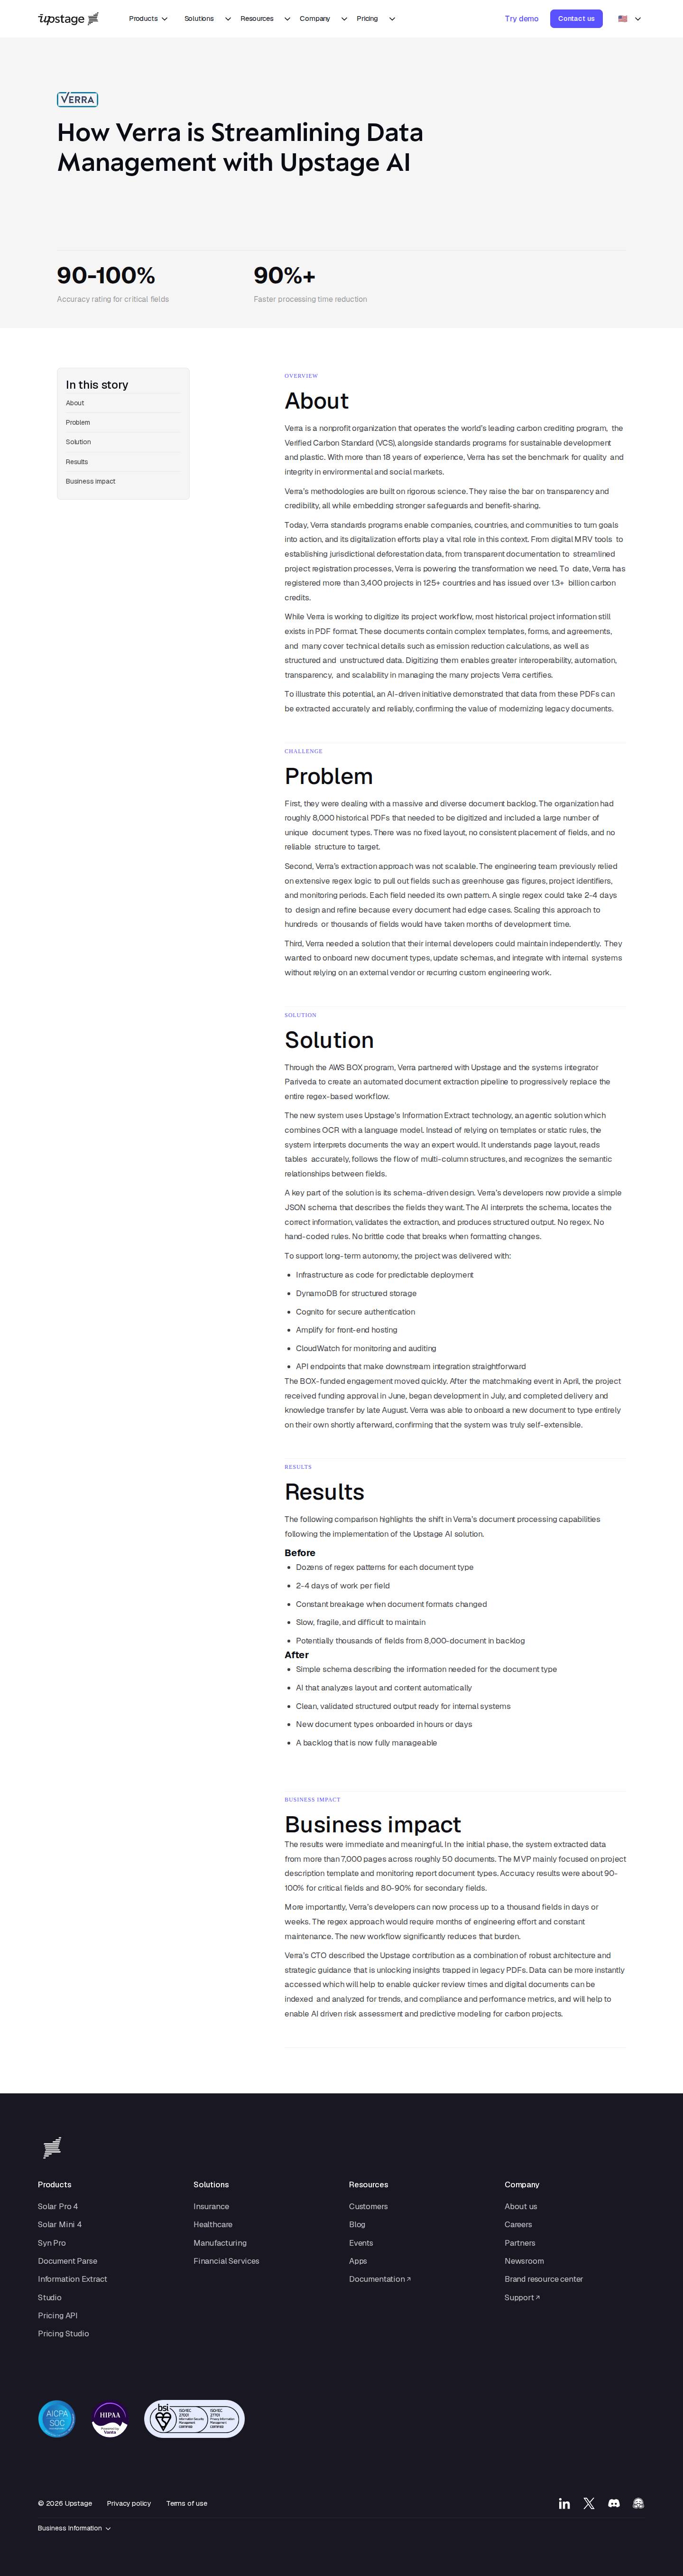
Verra uses Upstage's Information Extract to pull structured data from its historical project PDFs, replacing regex-based extraction with a JSON schema-driven pipeline. This lets its developers digitize a large backlog of varied documents and onboard new document types on their own.
More reported results
Figures published in Upstage’s case study. They are not independently measured by usedby.
Accuracy results were about 90- 100% for critical fields and 80-90% for secondary fields.
In the initial phase, the system extracted data from more than 7,000 pages across roughly 50 documents.
Other companies using Upstage
Customers across industries, with public evidence.
 AmwinsConfirmedBest OptionConfirmedConnectWaveConfirmed
 Hanwha LifeConfirmed
 The ChosunilboConfirmed
 Tricura Insurance GroupConfirmed
Go straight to the source
Based on Upstage’s published case study. We check the public evidence; the results are reported by the vendor.
upstage.ai- Last checked
- Nov 8, 2026
 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 90-100%Checked
The figure is on the page; its label is our wording.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Verra.
- Verra uses UpstageChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
Verra’s developers now provide a simple JSON schema that describes the fields they want. The AI interprets the schema, locates the correct information, validates the extraction, and produces structured output. No regex. No hand-coded rules.