The use case: how WolfBench deploys Daytona
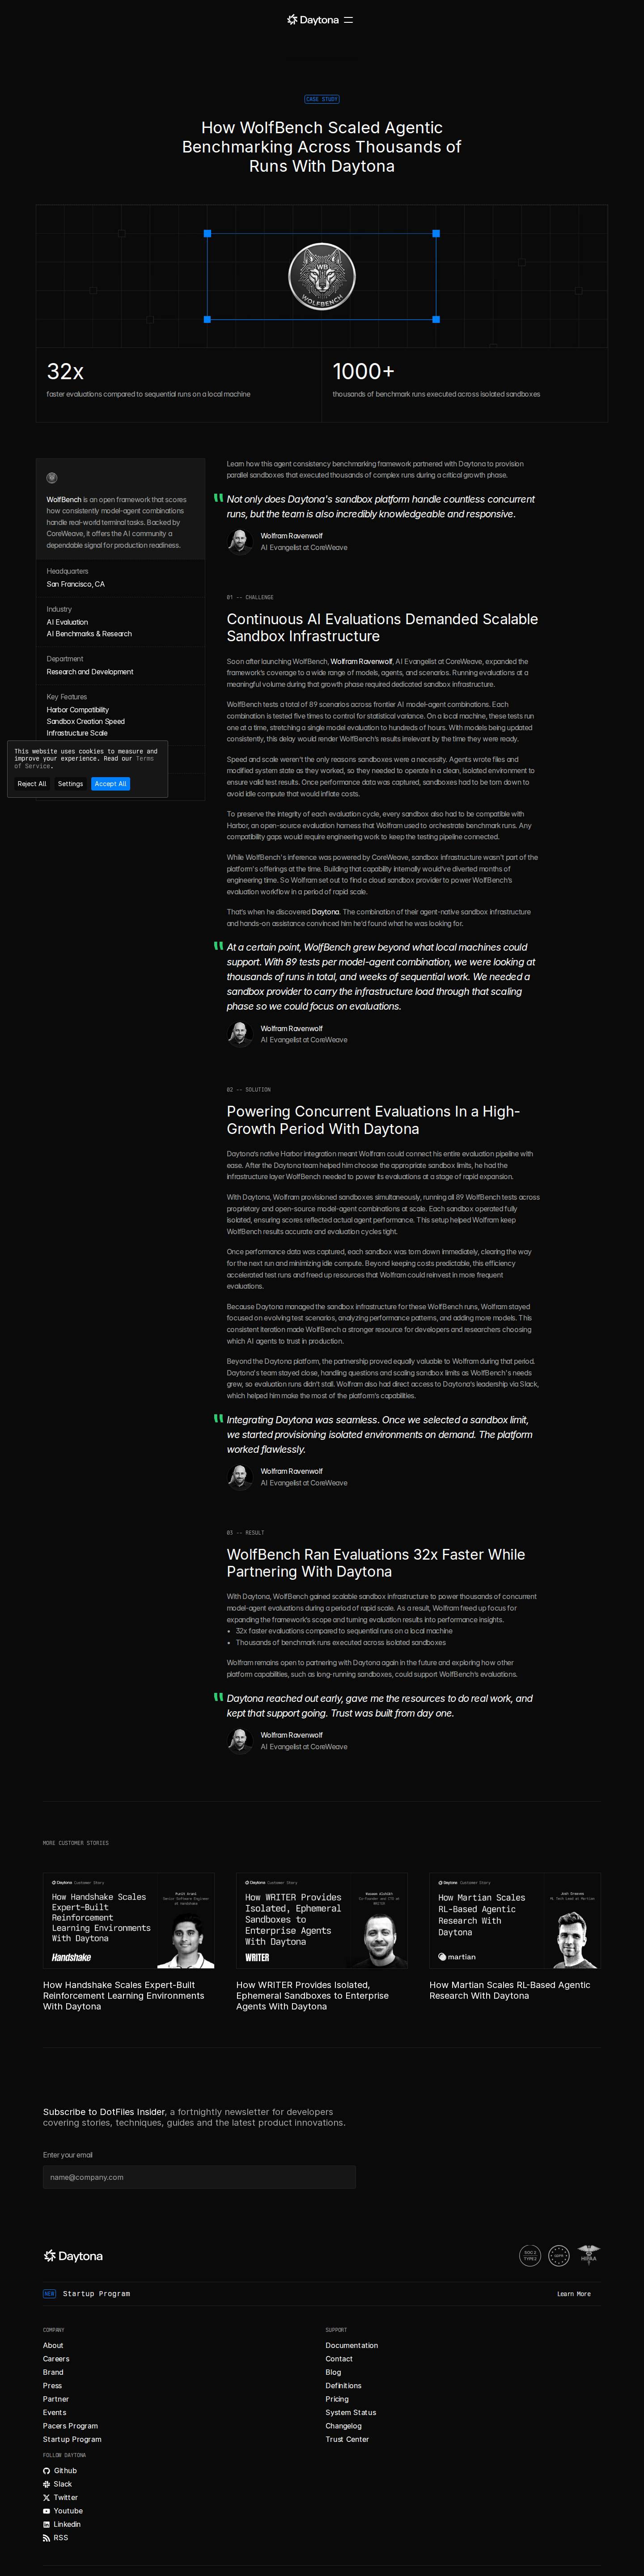
WolfBench runs its agent consistency benchmark by provisioning isolated Daytona sandboxes in parallel, so each model-agent combination is tested across all its scenarios without sequential local runs. Sandboxes are torn down once performance data is captured.
More reported results
Figures published in Daytona’s case study. They are not independently measured by usedby.
WolfBench tests a total of 89 scenarios across frontier AI model-agent combinations.
In the customer’s words
Integrating Daytona was seamless. Once we selected a sandbox limit, we started provisioning isolated environments on demand. The platform worked flawlessly.Other companies using Daytona
Customers across industries, with public evidence.
 AfterQueryConfirmed
 AsteroidConfirmed
 BenchFlowConfirmed
 CapyConfirmed
 HandshakeConfirmed
 Laude InstituteConfirmed
Go straight to the source
Based on Daytona’s published case study. We check the public evidence; the results are reported by the vendor.
daytona.io- Last checked
- Oct 27, 2026
 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 32xChecked
Printed word for word on the page, near the name of WolfBench.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of WolfBench.
- WolfBench uses DaytonaChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
With Daytona, Wolfram provisioned sandboxes simultaneously, running all 89 WolfBench tests across proprietary and open-source model-agent combinations at scale. Each sandbox operated fully isolated, ensuring scores reflected actual agent performance.