The use case: how Hebbia deploys Baseten
Hebbia runs a dedicated deployment of an open-source LLM on Baseten to serve latency-sensitive chat traffic for its financial institution customers. The setup uses KV-aware cache routing, speculative decoding and elastic GPU scaling.
More reported results
Figures published in Baseten’s case study. They are not independently measured by usedby.
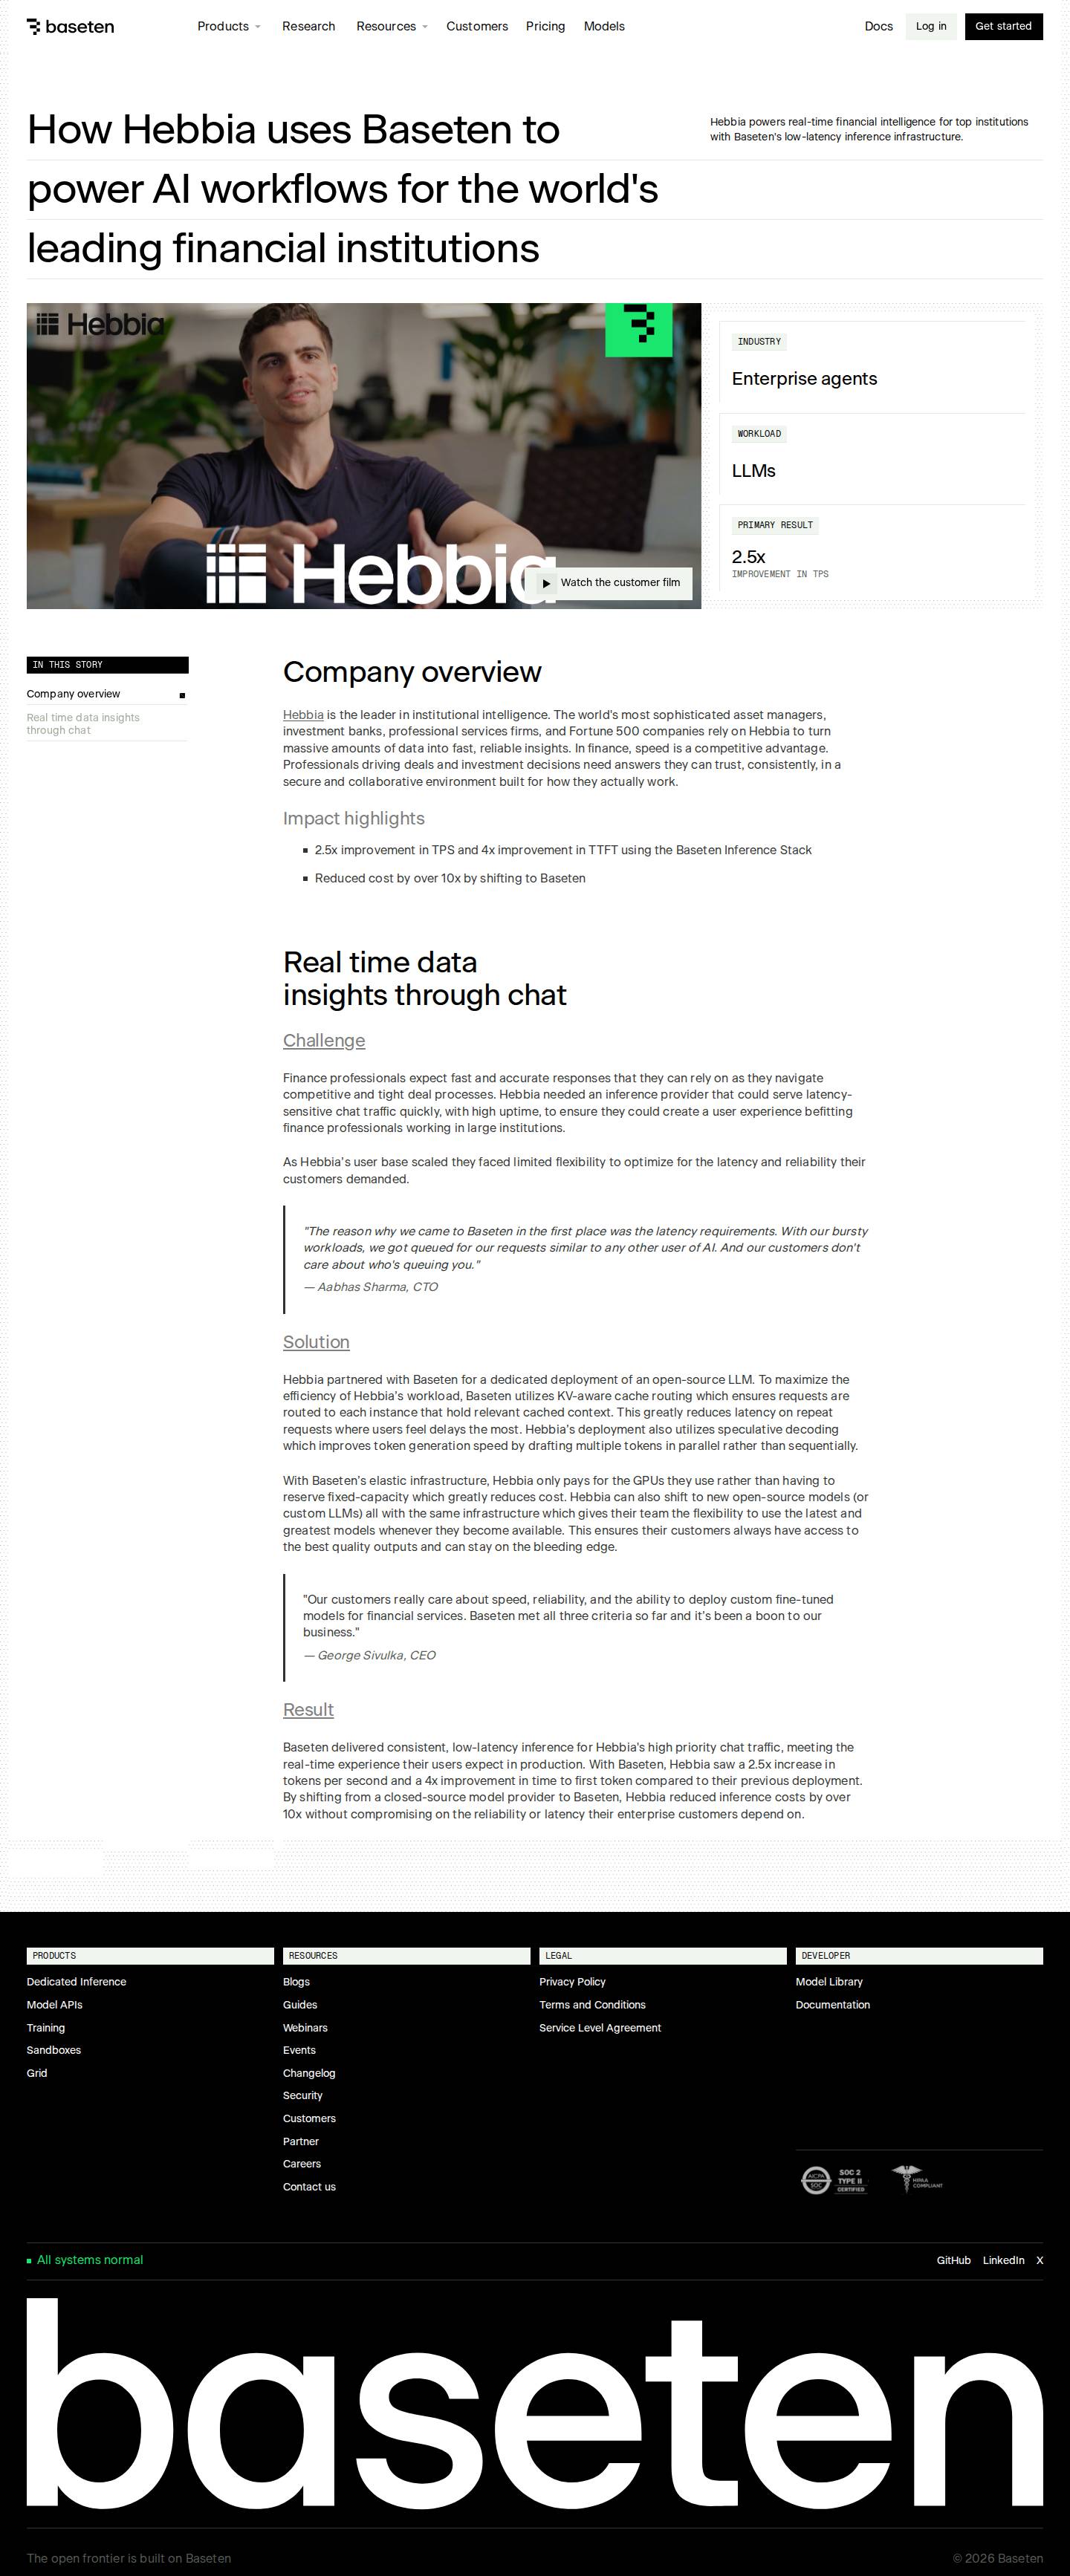
2.5x improvement in TPS and 4x improvement in TTFT using the Baseten Inference Stack
In the customer’s words
Our customers really care about speed, reliability, and the ability to deploy custom fine-tuned models for financial services. Baseten met all three criteria so far and it’s been a boon to our business.Other AI tools used by Hebbia
Other public relationships recorded on usedby.
 BraintrustConfirmed
 ClaudeConfirmed
 GeminiConfirmed
 CerebrasDeclared
 DatadogDeclared
 Fireworks AIDeclared
Baseten users in Artificial Intelligence
Companies in the same sector, with public evidence.
 EliseAIConfirmed
 GammaConfirmed
 Oxen AIConfirmed
 Parallel Web SystemsConfirmed
 PoolsideConfirmed
 RimeConfirmed
Go straight to the source
Based on Baseten’s published case study. We check the public evidence; the results are reported by the vendor.
baseten.co- Last checked
- Nov 11, 2026
 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 10xChecked
Printed word for word on the page, near the name of Hebbia.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Hebbia.
- Hebbia uses BasetenChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
By shifting from a closed-source model provider to Baseten, Hebbia reduced inference costs by over 10x without compromising on the reliability or latency their enterprise customers depend on.