The use case: how Cursor deploys Fireworks AI
Cursor, an AI-native code editor, runs a fine-tuned Llama-3-70b model for its Fast Apply feature on Fireworks AI's inference stack with a speculative decoding API, so large code edits are applied quickly.
More reported results
Figures published in Fireworks AI’s case study. They are not independently measured by usedby.
a ~9x speedup over their previous GPT-4 speculative edits deployment
achieving speeds of ~1000 tokens/s (approximately 3500 char/s) on a 70b model
In the customer’s words
...because it's way more performant than the open source engines and is what we use in production. our rl inference scales elastically and globally because of it. when we have low prod traffic we scale up RL, when we have high prod traffic, we scale down RL.Fireworks has been a key partner in helping us train and serve the models behind Cursor at scale. Their platform supports the high-throughput RL workloads and production inference required for Composer, giving us the speed, reliability, and efficiency to keep pushing the frontier of AI coding.Other AI tools used by Cursor
Other public relationships recorded on usedby.
Explore Cursor’s AI stack

Fireworks AI users in DevTools & Infrastructure
Companies in the same sector, with public evidence.
See all Fireworks AI customers
Go straight to the source
Based on Fireworks AI’s published case study. We check the public evidence; the results are reported by the vendor.
fireworks.ai- Source published
- Jun 23, 2024
- Last checked
- Nov 11, 2026
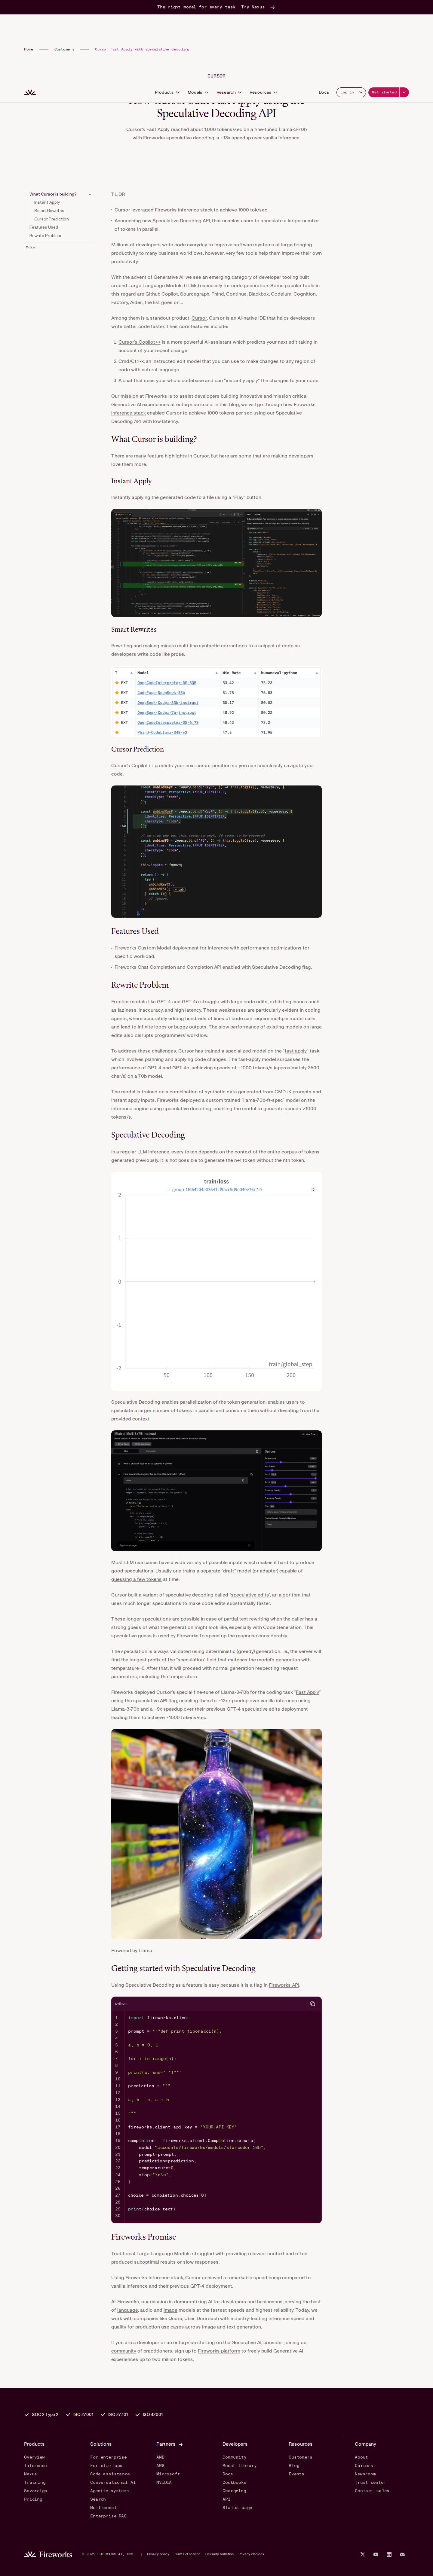 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: ~13xChecked
Printed word for word on the page, near the name of Cursor.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Cursor.
- The numbers in our summaryChecked
Each one is printed on the page.
- The publication dateChecked
Read from the page’s own metadata, never guessed.
- Cursor uses Fireworks AIChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
Fireworks deployed Cursor’s special fine-tune of Llama-3-70b for the coding task “Fast Apply” using the speculative API flag, enabling them to ~13x speedup over vanilla inference using Llama-3-70b and a ~9x speedup over their previous GPT-4 speculative edits deployment