The use case: how Wispr Flow deploys Baseten
Wispr Flow runs fine-tuned Llama models for real-time transcript cleanup on Baseten's dedicated deployments, hosted on AWS. The models and its speech recognition pipeline power voice dictation across applications, using Baseten's TensorRT-LLM engine builder, Chains framework and autoscaling GPUs.
More reported results
Figures published in Baseten’s case study. They are not independently measured by usedby.
To hit this latency target, the Llama model must consistently process and generate 100+ tokens in under 250 milliseconds.
In the customer’s words
With Baseten, we gained a lot of control over our entire inference pipeline and worked with Baseten’s team to optimize each step.Other AI tools used by Wispr Flow
Other public relationships recorded on usedby.
Explore Wispr Flow’s AI stack
Baseten users in Artificial Intelligence
Companies in the same sector, with public evidence.
 EliseAIConfirmed
 GammaConfirmed
 HebbiaConfirmed
 Oxen AIConfirmed
 Parallel Web SystemsConfirmed
 PoolsideConfirmed
Go straight to the source
Based on Baseten’s published case study. We check the public evidence; the results are reported by the vendor.
baseten.co- Last checked
- Nov 11, 2026
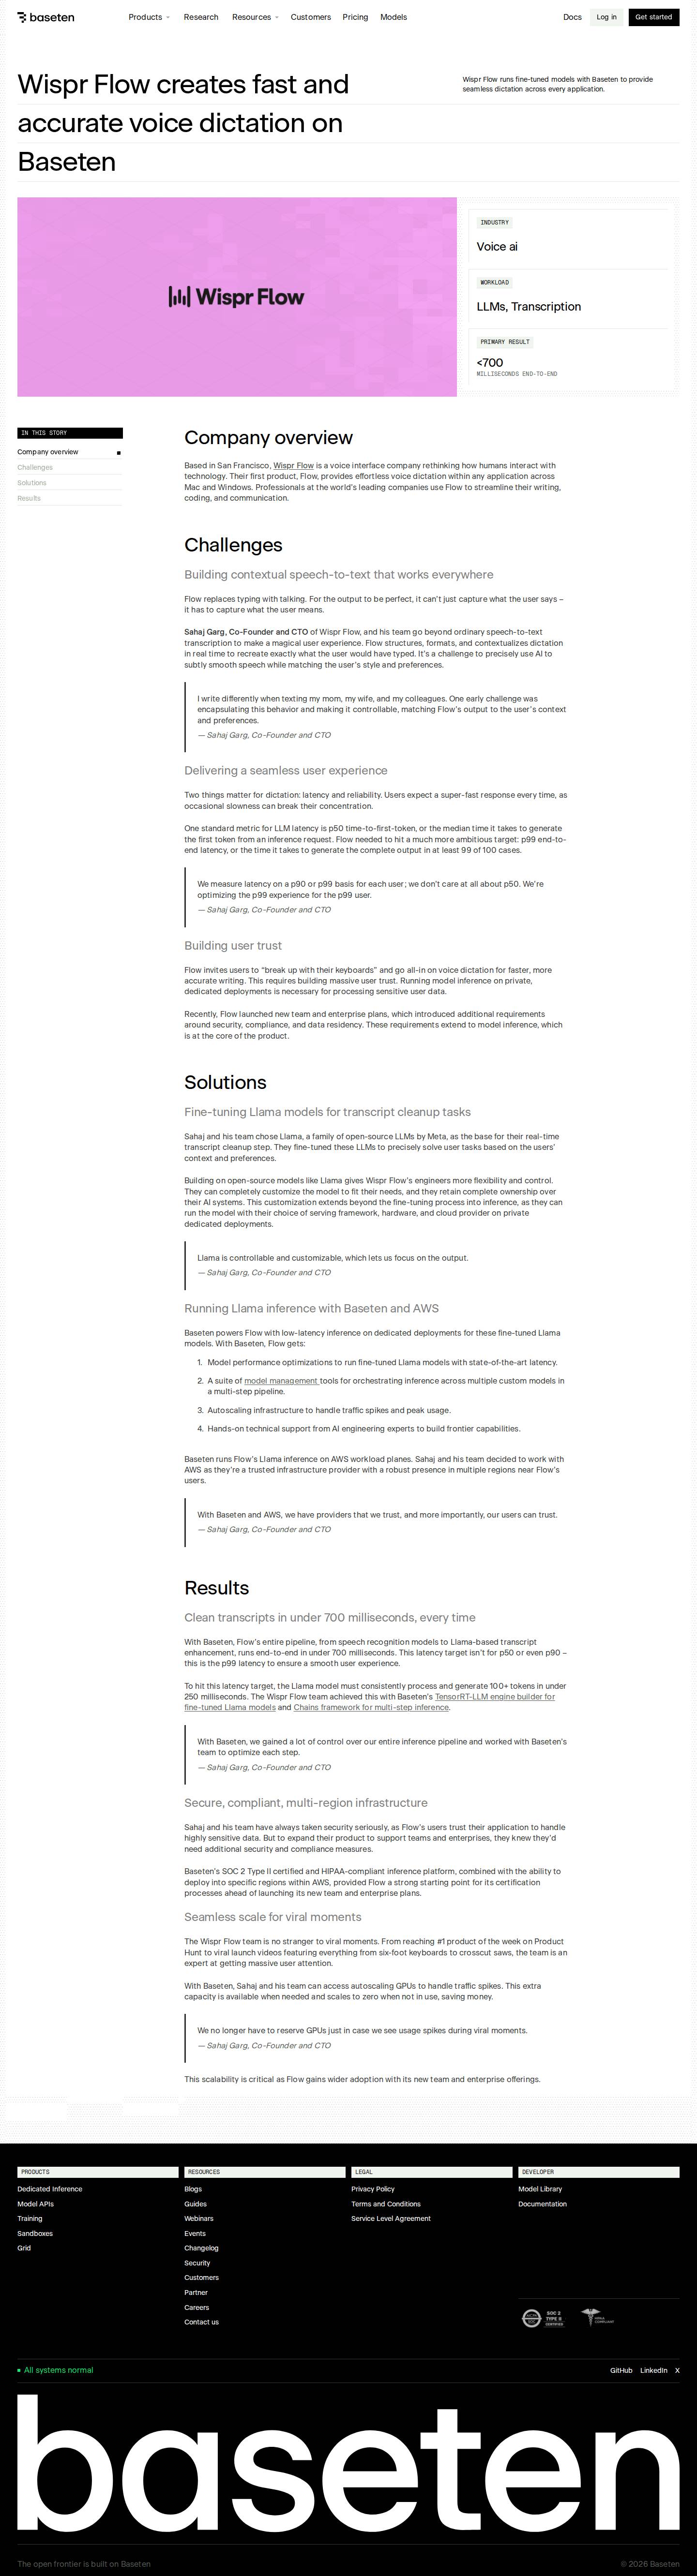 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The figure: 700 millisecondsChecked
Printed word for word on the page, near the name of Wispr Flow.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Wispr Flow.
- Wispr Flow uses BasetenChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
With Baseten, Flow’s entire pipeline, from speech recognition models to Llama-based transcript enhancement, runs end-to-end in under 700 milliseconds. This latency target isn’t for p50 or even p90 – this is the p99 latency to ensure a smooth user experience.