The use case: how Cartesia deploys Together AI
Cartesia runs production real-time voice serving and model training on Together AI's GPU clusters. It operates a custom inference engine for its State Space Model architecture with cluster-level access, and uses PCI-compliant environments for regulated enterprise customers.
In the customer’s words
Because our voice models use state space architectures, we need to run a purpose-built inference engine. Together AI gives us the compute and cluster-level access we need—down to the filesystem and SSH permissions—so we can optimize our serving stack exactly how we want. They manage the heavy lifting of the hardware orchestration and ingress, and we get the low-level control required to hit our streaming latency targets.Other AI tools used by Cartesia
Other public relationships recorded on usedby.
Explore Cartesia’s AI stack
Together AI users in Artificial Intelligence
Companies in the same sector, with public evidence.
 Arcee AIConfirmed
 DecagonConfirmed
 Deep CogitoConfirmed
 Dippy AIConfirmed
 HedraConfirmed
 LegionEdgeConfirmed
Go straight to the source
Based on Together AI’s published case study. We check the public evidence; the results are reported by the vendor.
together.ai- Last checked
- Oct 3, 2026
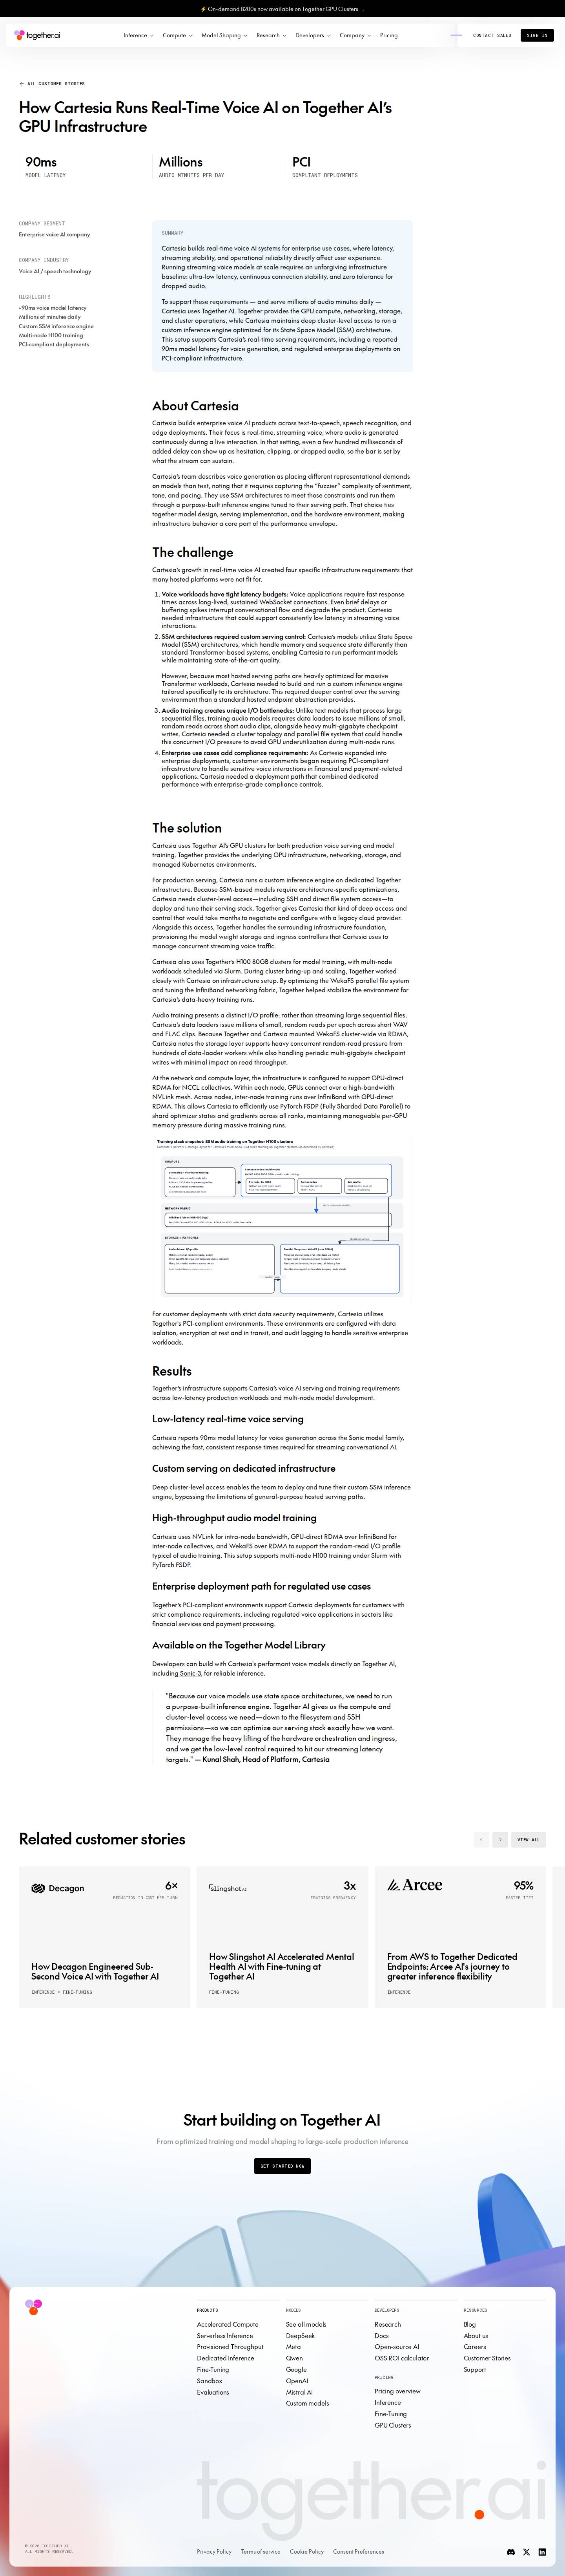 Open source capture
What the story claims, and what we checked
What we compared with the page.
- The passage quoted aboveChecked
Copied word for word from the page, near the name of Cartesia.
- Cartesia uses Together AIChecked
Confirmed line.
- The result itselfNot checked
We quote it; we did not measure it.
Cartesia reports 90ms model latency for voice generation across the Sonic model family, achieving the fast, consistent response times required for streaming conversational AI.